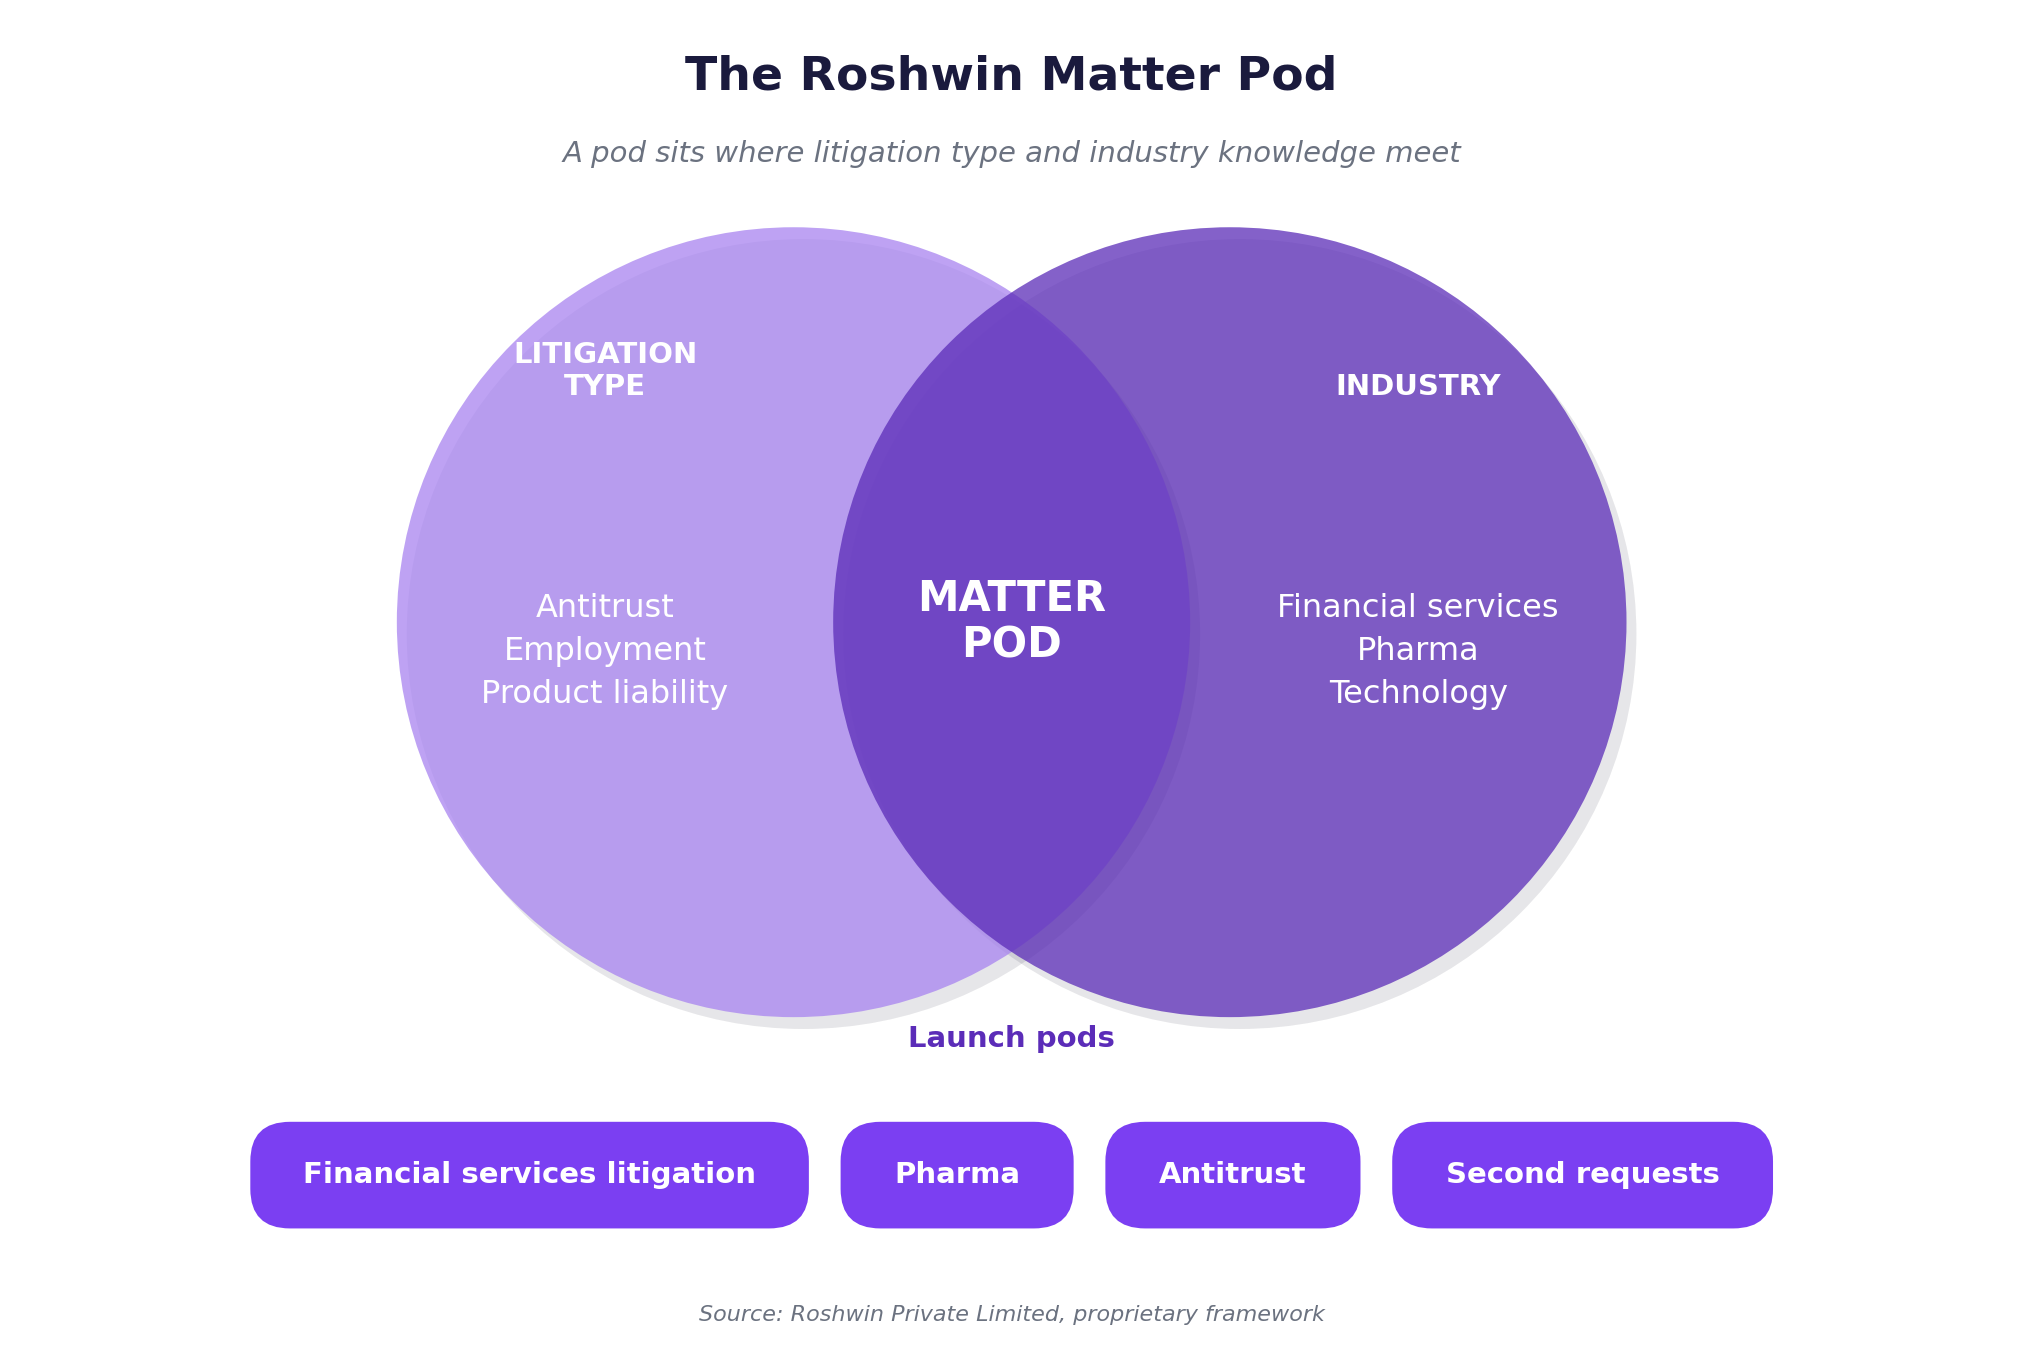
Matter Pods: Why Specialized Review Teams Beat Generic Review Pools
Why the team reviewing your documents should understand your case before it opens the first one, and how to build that into the workflow.
Metadata captured at scale
Standard objective fields such as date, author, recipients, document type and title, plus any additional fields your matter needs, coded consistently with an AI first pass and human validation.

The challenge
A review platform is only as useful as the metadata behind it.
Field set: standard fields plus any your matter needs
First pass for speed and uniformity
Validation and sampling to hold quality
Searching, sorting and logging ready
Scanned records, hard-copy productions and legacy files often arrive with little or no usable metadata. Without it, searching, sorting, privilege logging and exhibit preparation slow to a crawl.
Our proprietary approach lets AI draft the objective coding so large volumes move quickly and uniformly, while reviewers check and sample the output against an agreed protocol. The field set is flexible: we start from the standard bibliographic fields and add whatever your matter requires at setup. The result is clean metadata loaded straight into your platform.
Standard fields such as date, author, recipients, document type and title, extended with any custom fields you need.
AI drafts the coding, so large volumes move quickly and uniformly.
Reviewers check and sample the output to hold quality.
We prove the approach on a small sample with you first, then scale. Here is how the work flows, and where AI carries the load versus where our attorneys apply judgement.
Technology where it adds value
An indicative view of how work is shared between AI and our attorneys at each stage. Judgement, protocol and sign-off always stay with people.
Standard and custom fields, formats, conventions and edge cases agreed with your team.
Every agreed field drafted across the full set.
Reviewers check, correct and sample against the protocol.
Clean metadata delivered in your load file format.
What you receive
Clean, consistent metadata loaded into your review platform, so searching, sorting and logging work from day one.
Where it fits best
The attorney who scopes your work shares pricing up front. These are the models that typically suit bibliographic coding.
Best for
Defined projects, such as a CLM assessment or a contract clean-up.
How it is billed
One price for an agreed scope and outcome.
Best for
Variable volume, such as document review or abstraction.
How it is billed
Per document or per contract, with a ceiling on total spend.
Best for
Ongoing work, such as platform operations or monitoring.
How it is billed
A monthly fee for a dedicated team, scaled up or down with notice.
Best for
Programmes that mix a project with steady run work.
How it is billed
A fixed fee to build, then a unit rate or team fee to run.
Any field your matter needs. We start from the standard bibliographic fields, such as date, author, recipients, copyees, document type and title, and add custom fields at setup. The field set is not fixed.

Why the team reviewing your documents should understand your case before it opens the first one, and how to build that into the workflow.

How human-in-the-loop AI is reshaping document review while maintaining the precision and defensibility that courts demand. The role of trained professionals alongside intelligent systems.

Specialist pods design, calibrate and run defensible document review on your platform, combining linear, active learning and GenAI first-pass workflows.

Source-linked, human-validated case chronologies built from thousands of documents, by whole case or by issue, claim or party.
Tell us the fields you need, standard or bespoke. We set up the coding, validate it and deliver clean, load-ready data on your platform.
Start a Conversation